A Sourcing Desk for AI TeamsThe Right Compute, Faster

Deploy frontier open-weight and custom models with efficiency you can measure. Up to 70% cheaper than hyperscalers, for more tokens per dollar and healthier margins.
Visa
Adyen
Dynamic Yield
Harvey
Multimodal
Tata 1mg
Mistral AI
Zoho
Midjourney
HDFC Ergo

Compute. Find reliable compute operated globally from a single GPU to largest clusters.

On demand

Instant access to 1-256 GPUs.
Use your GPUs across clouds in a single platform.

1.1SLURM, K8s OrchestrationOrchestrate dynamic workloads with enterprise-grade scheduling and container automation.
1.2Infiniband NetworkingScale distributed training with high-bandwidth interconnects across nodes.
1.3Grafana Monitoring DashboardsVisualize metrics in real time with customizable dashboards for full system observability.
REQUEST COMPUTE

FIG.1

NVIDIA

H200

Availablex2 · x1

$1.99/HR

80 GB VRAM·184 GB RAM·32 vCP
NVIDIA

H200

Availablex2 · x1

$1.80/HR

80 GB VRAM·184 GB RAM·32 vCP
NVIDIA

H200

Availablex2 · x1

$1.23/HR

80 GB VRAM·184 GB RAM·32 vCP
NVIDIA

H200

Availablex2 · x1

$0.47/HR

80 GB VRAM·184 GB RAM·32 vCP
NVIDIA

B300

Availablex2 · x1

$4.99/HR

288 GB VRAM·480 GB RAM·48 vCP
NVIDIA

B200

Availablex2 · x1

$3.49/hr

192 GB VRAM·384 GB RAM·32 vCP
NVIDIA

H200

Availablex2 · x1

$3.14/HR

141 GB VRAM·182 GB RAM·44 vCPUs
NVIDIA

H100

Availablex2 · x1

$2.43/HR

Spot 0.94/HR

80 GB VRAM·185 GB RAM·32 vCPUs
NVIDIA

GH200

Availablex2 · x1

$3.14/HR

96 GB VRAM·480 GB RAM·72 vCP
NVIDIA

RTX Pro 6000

Availablex2 · x1

$3.14/HR

96 GB VRAM
NVIDIA

A100

Availablex2 · x1

$3.14/HR

80 GB VRAM
NVIDIA

A40

Availablex2 · x1

$3.14/HR

48 GB VRAM

Liquid Reserved Clusters

Request large-scale clusters from 50+ providers.
Sell-back idle GPUs to our spot market.
1.1Get quotes from 50+ datacenters within 24 hoursOne request, parallel bids for options, from H100, H200, to  B200, B300, GB300 NVL72
1.2Re-sell idle GPUs back to our spot marketResell idle node on our spot market or put on our spot market with no manual ops. Reclaim capacity instantly when you need it
1.3Direct assistance from our research and infra engineering teamDedicated solutions engineer from cluster bring-up through steady-state

FIG.2

Enter GPU name..

NVIDIA

B300 SXM6 x 512

SXM6
3-YEAR RESERVED

$5.00/HR/GPU

TOTAL $2,560/hr

Your workloads
Idle · resold
Idle · unsold
Reserved cost (3yrs)
$67,276,800
Idle hrs resold
6,727,680 hrs
Cost of idle capacity
$33,638,400
Revenue at $8.00/hr/gpu
$53,821,440

Profit on idle capacity

6,727,680 idle hrs resold at $8.00/hr

+$20,183,040
Operate GPU capacity? List it with ClusterBid

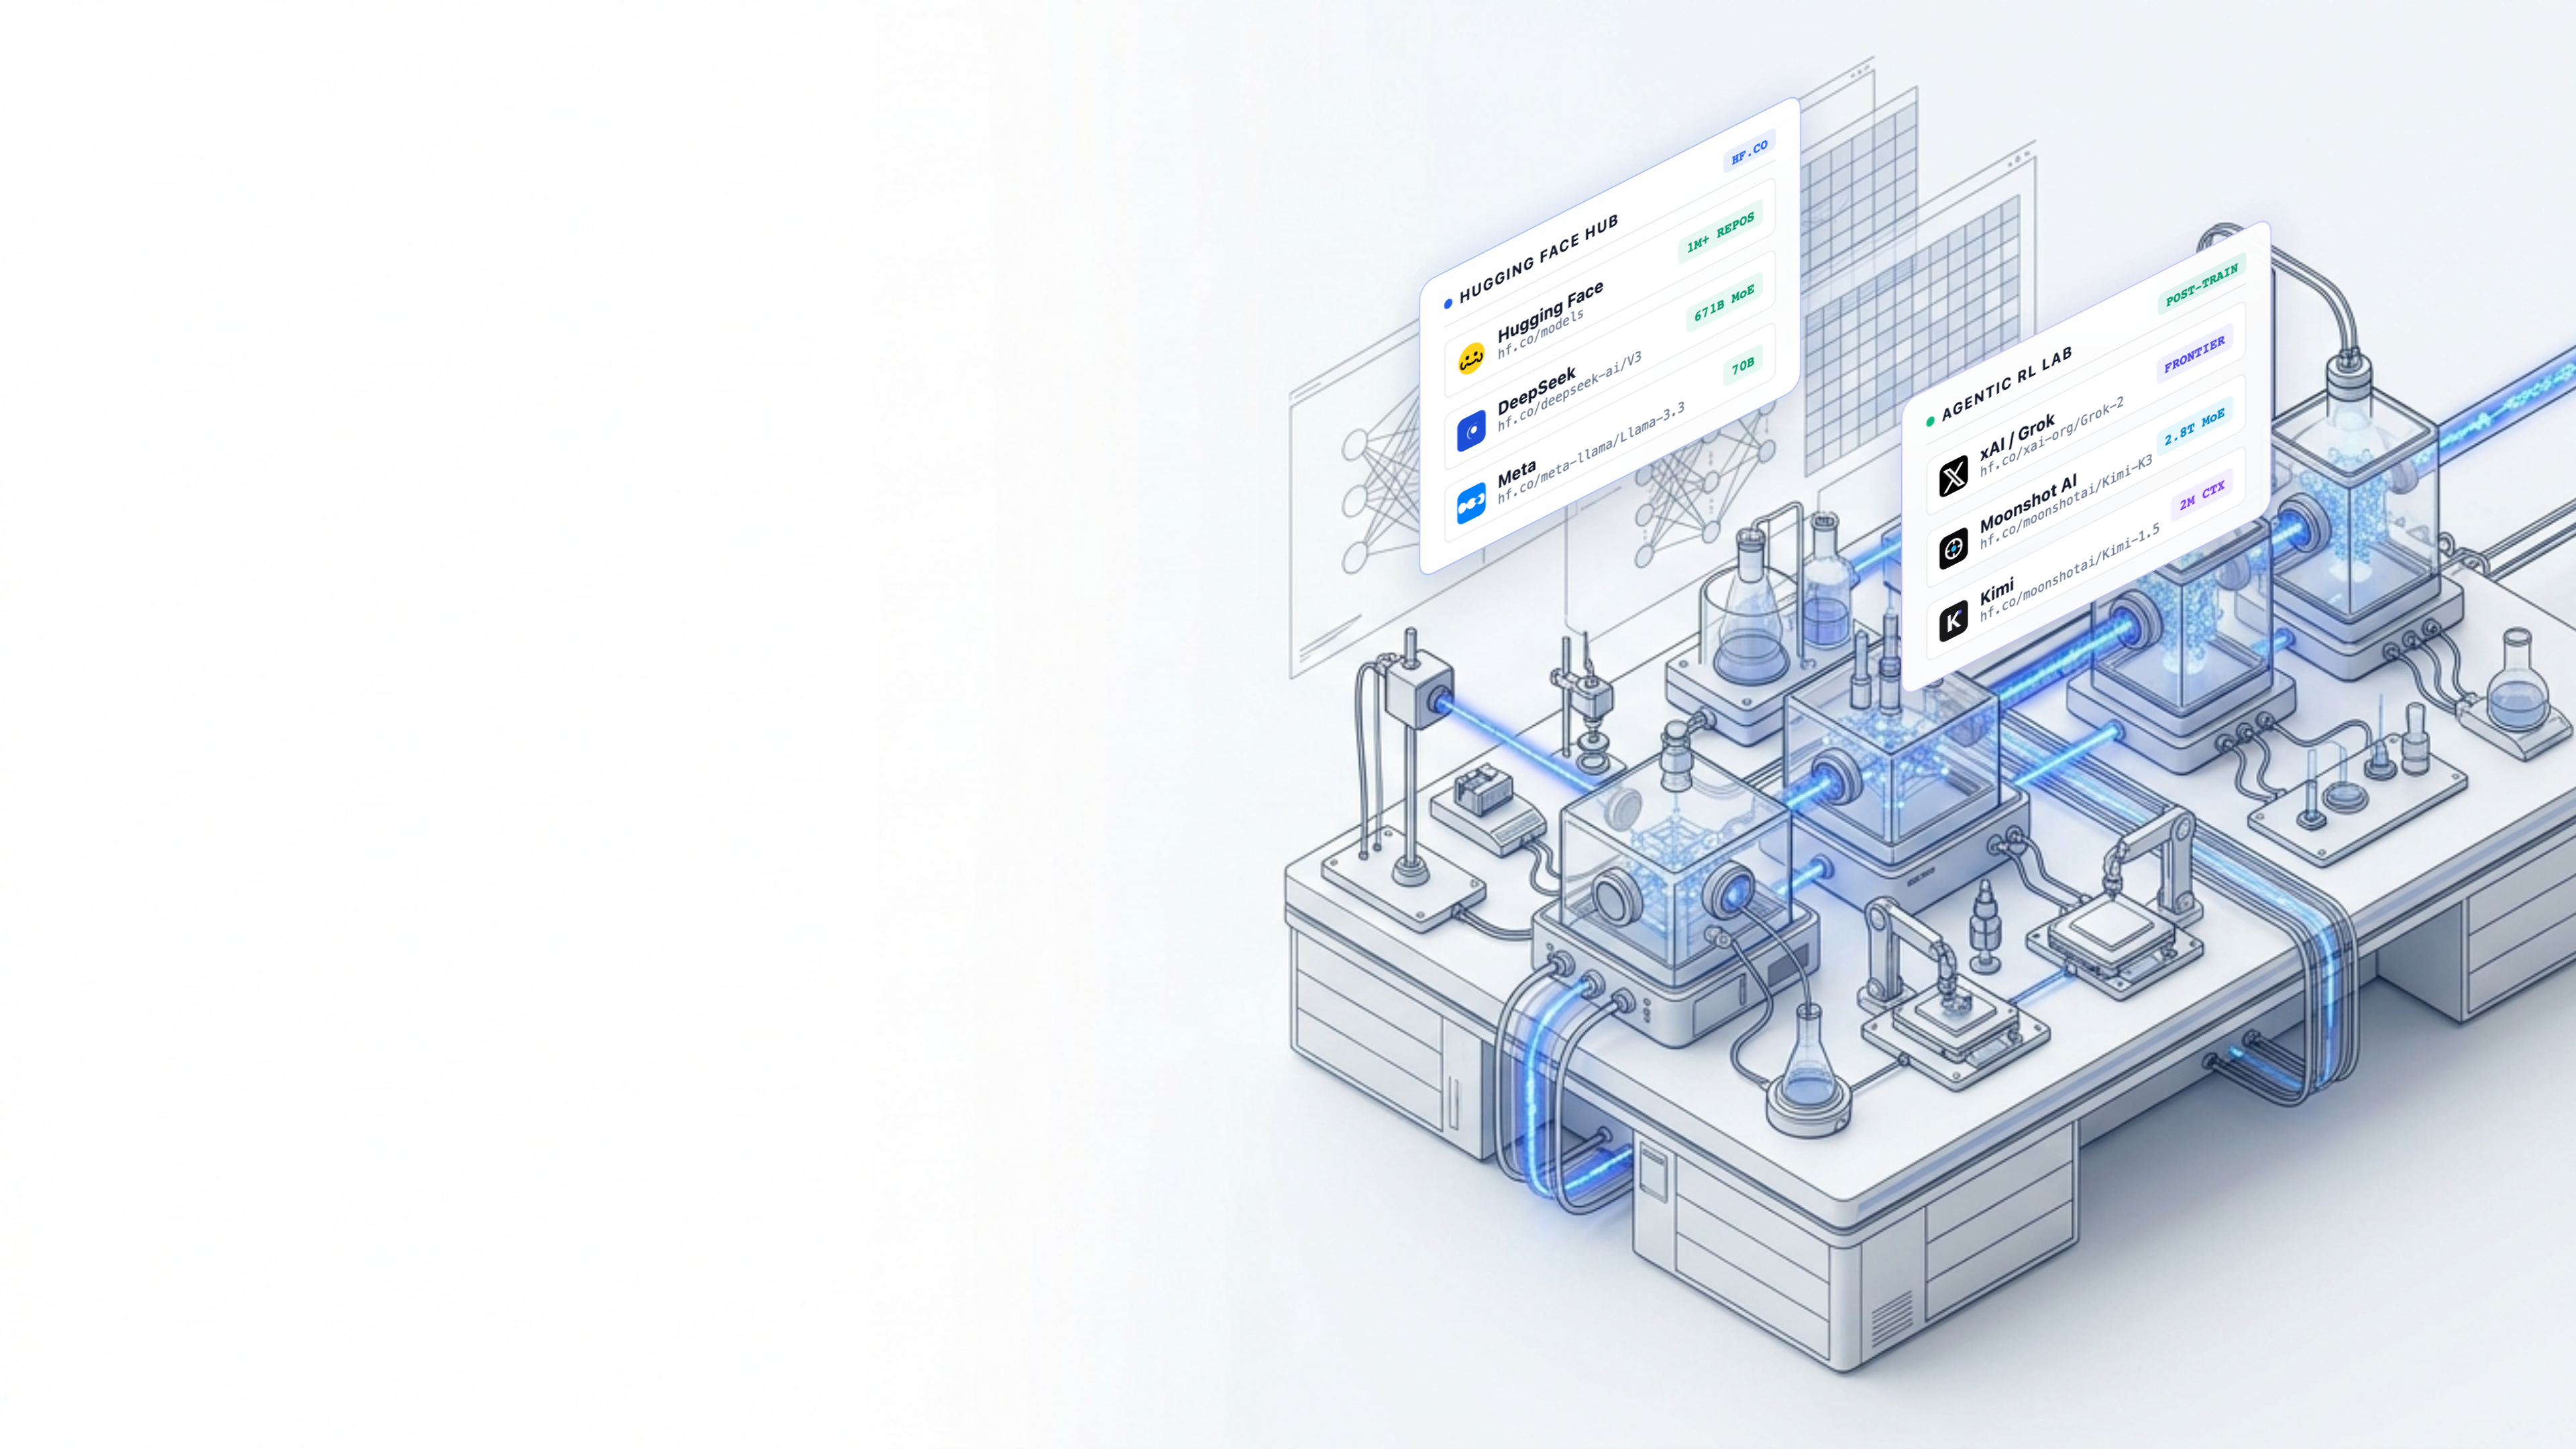
Lab. Run any open-source model from Hugging Face and post-train it into a self-improving agent

FIG.3
01Open-Source Models

Run any open-source model from Hugging Face. Pick a model on the Hub and it's serving on ClusterBid compute in minutes.

1.11M+ Hugging Face models, one search away
1.2From 1B to 2.8T - Kimi, DeepSeek, Qwen, GLM and more
1.3Weights pulled straight from the Hub. No conversion, no re-upload
GPU RECOMMENDER

FIG.4

Reward0.01
10.80.60.40.20
max_steps10,000
rollouts_per_example19
seq_len4
batch_size65536
max_tokens256
learning_rate0.00005
02Hosted Training

Train large-scale models optimized for agentic workflows.

2.1Train on 2,500+ RL environments
2.2Managed training workflows with full visibility and control
2.3Hands on support from our applied research team
REQUEST COMPUTE

FIG.5

03Inference

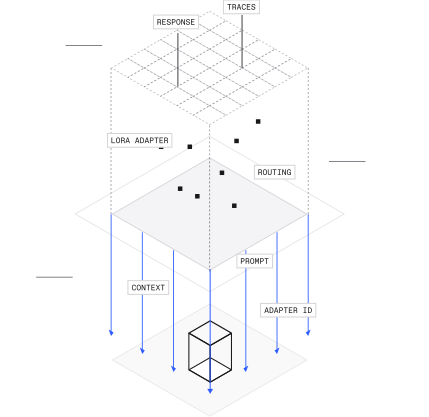
Dedicated or serverless inference for your custom models, with native LoRA support.
3.11-click deployment for any fine-tuned model
3.2LoRA adapters served alongside base models
3.3Zero config. No setup.
Book a Call

Inference. Serve open-source and custom models
through the same stack that trains them.

Dedicated inference, pay-per-token LoRA serving, and serverless APIs-all in one loop that turns traces into better models and cheaper intelligence your business owns.
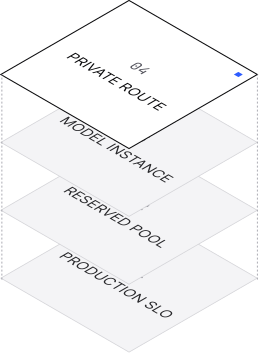
Dedicated deploys
Production serving capacity optimized around customer use cases, private routing, latency, reliability, and custom model requirements.
LoRA inference
Pay-per-token serving for adapters trained with Lab, so teams can deploy customized behavior without copying the base model.
Serverless APIs
OpenAI-compatible access to base models with efficient routing, selected first-party hosting, and a path into dedicated capacity.

Turn production traces into the next training run.

Capture traces, cluster failures, convert high-value misses into environments and evals, then train adapters that make the production model cheaper, more reliable, and more specific to your business.
Compliant & secure. Compliance is a filter here, not a footnote. A facility
does not get on ClusterBid until it clears every audit below.

Certifications

Cleared end to end before a facility is allowed to quote.
ISO 27001
ISO/IEC 27001:2022

Information security management audited and certified end to end by an accredited body.
SOC 2 Type I
AICPA Trust Services - Point-in-time

Controls examined and attested at a fixed point in time.
SOC 2 Type II
AICPA Trust Services - Continuous window

The same controls evidenced continuously across a full audit window, not a single day.
HIPAA
45 CFR Part 164

Protected health information handled to standard for clinical and life-science workloads.

FIG.7

Facility floor
Uptime tier
Tier III or Tier IV
Power
N+1 redundancy, minimum
Cooling
Redundant loops, N+1 minimum
Network
Carrier and fiber diverse
Provider
Diligence cleared before listing